
Wednesday, September 26, 2007
0
Saturday, September 08, 2007
2
"The Solution"
The following is a link to a transcript, released today, of a speech titled "The Solution" delivered by Usama Bin Laden, the FBI's most wanted terrorist. The speech is addressed to the American people, commemorating the sixth anniversary of the 9/11 attacks. It is Bin Laden's first public communications in almost three years. I have posted the link to the PDF of the transcript here because, ironically, it is quite hard to find it on any of the news sites.
The speech itself is well written and worth a read. Keep in mind that it is a translation from Arabic.
"The Solution" transcript.pdf
The speech itself is well written and worth a read. Keep in mind that it is a translation from Arabic.
"The Solution" transcript.pdf

Tuesday, August 07, 2007
0
The Automatic Brain
Have you ever driven to work, or walked to class and later had no memory of how you actually got there? Have you ever really needed to study for a test, but just found it impossible to concentrate, no matter what you tried? One theory that can explain this seemingly irrationality is that there is a second brain, a parallel brain, which operates below the observable threshold of consciousness. This is the primitive brain, whose structure we share with other animals.
This primitive brain has a much larger memory capacity. In contrast, the conscious brain has a rather limited memory; studies have shown that people generally can only keep about 7 numbers in our heads. That is why phone numbers in the US have that length.
Some would argue that this subconscious brain is what distinguishes people from each other mentally. This is what some people would define as experience. Observe the people’s reasoning and rationalization patterns. Are they all that different? If they were, we would not be able to hold a logical discussion. It is the primitive brain that distinguishes two people.
But what distinguishes humans’ and machines’ "brains"? Machines have an enormouse advantage over the conscious "reasoning" brain. A machine can store much more than 7 items in short-term memory. Also, the execution speed of sequential reasoning operations in a machine is much faster than in a human’s conscious brain. This is because human brain circuits are limited in their operation by chemical "neurotransmitters" that are physically bound by diffusion speed. Therefore latency of information transfer in humans is higher.
Humans are no match for machines in what you might consider the highest form of human ability, "logical reasoning." In fact there are many well-known efficient algorithms for performing this process.
However, humans do have advantages over machines. The advantage is in this primitive, animal brain. This subconscious brain has massive parallelism, which allow data storage and computation to happen simultanesouly across all circuits. This tradeoff of latency for massive bandwidth have allowed humans to outperform computers in most interesting tasks.
This advantage may be only temporary, however. Although the machines were initially designed for sequential execution, recently we have seen more and more growth in developing parallel computation. Large data-intensive parallel systems have been developed. Parallel hardware and parallel algorithms have allowed new types of programs, such as entire-genome mappers, world-champion chess programs, and search engines. Human brain evolution is relatively fixed. Machine brain evolution seems to be exponential. The cross-over point will be where amazing things start to happen.
© 2005
This primitive brain has a much larger memory capacity. In contrast, the conscious brain has a rather limited memory; studies have shown that people generally can only keep about 7 numbers in our heads. That is why phone numbers in the US have that length.
Some would argue that this subconscious brain is what distinguishes people from each other mentally. This is what some people would define as experience. Observe the people’s reasoning and rationalization patterns. Are they all that different? If they were, we would not be able to hold a logical discussion. It is the primitive brain that distinguishes two people.
But what distinguishes humans’ and machines’ "brains"? Machines have an enormouse advantage over the conscious "reasoning" brain. A machine can store much more than 7 items in short-term memory. Also, the execution speed of sequential reasoning operations in a machine is much faster than in a human’s conscious brain. This is because human brain circuits are limited in their operation by chemical "neurotransmitters" that are physically bound by diffusion speed. Therefore latency of information transfer in humans is higher.
Humans are no match for machines in what you might consider the highest form of human ability, "logical reasoning." In fact there are many well-known efficient algorithms for performing this process.
However, humans do have advantages over machines. The advantage is in this primitive, animal brain. This subconscious brain has massive parallelism, which allow data storage and computation to happen simultanesouly across all circuits. This tradeoff of latency for massive bandwidth have allowed humans to outperform computers in most interesting tasks.
This advantage may be only temporary, however. Although the machines were initially designed for sequential execution, recently we have seen more and more growth in developing parallel computation. Large data-intensive parallel systems have been developed. Parallel hardware and parallel algorithms have allowed new types of programs, such as entire-genome mappers, world-champion chess programs, and search engines. Human brain evolution is relatively fixed. Machine brain evolution seems to be exponential. The cross-over point will be where amazing things start to happen.
© 2005
Tuesday, May 29, 2007
1
Meme Representation in Communities
 I wrote previously on clip culture, the trend of consuming content in smaller snippets (blogs, TV news, youtube, twitter) rather than in longer form (books, journal articles, films, Ph.D. dissertation). One perhaps non-trivial consequence is that shortening the form of communication actually changes the representation and content of the message. The shortened-form is not simply a summarized version of the original events and information.
Many years ago, when I was young and even more foolish than I am now, I tried writing a intelligent software algorithm for automatically trading stocks. These types of automated trading programs are commonly utilized by hedge funds and constitute a good portion of the current trading activity in our stock market. My idea was to have the software automatically analyze online news and market data and predict the direction on stocks using statistical machine learning methods. The program would be able to react much faster than it would take a human to read and understand news articles from thousands of sources.
Sounds like a lovely idea, right?
Well I'm not a billionaire today, so it obviously didn't work. And I'll tell you why. Essentially, predicting a stocks value reduces to predicting what people, in aggregate, think of a stock. In this regard, the content on the web is not an accurate representation of reality. Here's a crude demo. Consider for example the occurrences of the phrase "Microsoft is good" vs. "Linux is good" on the web. (Go ahead, Google it) You might falsely conclude from this data that you should be buying Red Hat stock and dumping MS shares. However, we all know that this is just selection bias. For another example, check out We Feel Fine by Sepander Kamvar(a Stanford professor, Google employee, and great guy, btw). This is a cool design experiment and has some neat graphs, but I doubt that those percentages are an accurate representation of how Livejournal users actually feel. These kinds of aggregations always tend towards the manic-depressive while most of us just feel normal most of the time. The content of the web is not an accurate representation of reality, and this selection bias is exacerbated by clip culture.
This is not a new disease of the blogsphere though, but a condition that has always existed in media. Anyone that's browsed a bookstore or watched TV can observe that it's the loud, the sensationalistic that gets facetime. And this misrepresentation is an important issue, because you can't expect every single person to have to the time to check all the facts. It's not practical. Whether you like it or not, people go by what they hear and see and this slowly shapes and molds their perspectives and behaviors.
What is new though, is that for the first time in history we might be able to address these problems effectively. Because of the internet, collecting and aggregating all the information together is no longer an issue. Now that the information can be aggregated to one place, the problems of representation and fact-checking can be attacked head on. In the future, intelligent software agents will be able to do this fact-checking for us at a scale that no human reader could possibly do in a lifetime. These agents will classify all of the viewpoints on a topic and determine which are legitimate arguments and which are just re-hashings of old propaganda.
Finally, the average citizen will have a weapon against the rising influence of mass media.
Thursday, April 26, 2007
1
I Named a Chinese Book
So, one of my Aunties is a quite well-renowned chef and cooking instructor in Taipei. She has previously published several of her cookbooks and now lives in Toronto, where she continues to give master classes in Chinese cooking. For the past few years, she has been working on her latest book, which is also a Chinese cooking book, but presents the dishes in a style reminiscent of French cuisine. Her book is titled "中菜西吃", which literally translates into something like "Chinese-Dishes-Western-Eating". Basically, the connotation is that while the foods and recipes are traditional Chinese dishes, the presentation, or display is in a more non-traditional Western-like style.
Anyways, the literal translation obviously doesn't make for a very attractive book title, and she asked many of her Canadian friends for suggestions for the English title of the book, the book being completely bilingual throughout. Not satisfied with any of the suggestions, she called me up when I was in Taiwan to get my recommendation. I actually gave this quite a bit of thought, in order to come up with something catchy. Anyways, below is my end result (click to view detail) , which should be published later this year. What do you think?

Congratulations, Auntie!
Anyways, the literal translation obviously doesn't make for a very attractive book title, and she asked many of her Canadian friends for suggestions for the English title of the book, the book being completely bilingual throughout. Not satisfied with any of the suggestions, she called me up when I was in Taiwan to get my recommendation. I actually gave this quite a bit of thought, in order to come up with something catchy. Anyways, below is my end result (click to view detail) , which should be published later this year. What do you think?

Congratulations, Auntie!
Wednesday, April 25, 2007
0
Speech Synthesis + Wikipedia
Ever simply wanted an MP3 of a Wikipedia article that you could take on the go in your Ipod?? Ever wanted to save a bunch of articles so that you could listen to them during rush hour traffic??
Yeah, neither did I.
However, today I found myself writing a quick script to do just that and if you by chance answered "yes" to any of those questions above then you are in luck! It's almost as simple as it could possibly be. You just supply the topic in the URL and the script generates a direct download of the MP3 in response.
The basic format I use looks like this: http://madfast.com/wikiread.cgi?q=[YOUR QUERY]. There are also a bunch of secret parameters I added that can be used to change the voice and file format.
Here are some examples:
Yeah, neither did I.
However, today I found myself writing a quick script to do just that and if you by chance answered "yes" to any of those questions above then you are in luck! It's almost as simple as it could possibly be. You just supply the topic in the URL and the script generates a direct download of the MP3 in response.
The basic format I use looks like this: http://madfast.com/wikiread.cgi?q=[YOUR QUERY]. There are also a bunch of secret parameters I added that can be used to change the voice and file format.
Here are some examples:
Go crazy.
http://madfast.com/wikiread.cgi?q=Robot
http://madfast.com/wikiread.cgi?q=Computational Biology
http://madfast.com/wikiread.cgi?q=台灣
Wednesday, February 21, 2007
0
On Clip Culture
One of the things that concerns me is that recently a vast majority of my information processing is reading these “snippets” of information instead of longer, more meaningful discussions. It’s not just a consequence of using Diffbot but I think where internet culture is headed towards– YouTube epitomizes the short-attention span cinema that is the trend. Perhaps due to the sheer number of news sources, these “info clips” are the only way to aggregate all these disparate sources sanely. Certainly its not for lack of longer original sources on the web. Plenty of journals and books are available online and corporations and governments publish many of their proceedings now in electronic documents online. The problem is current technology can't really deal with these types of sources. Have you ever had Google return a search result to U.S. Constitution or perhaps some company's SEC filing where the "real answers" might lie?
The hope of AI is the hope that we will eventually have a technology that can synthesize all these threads of information from the original sources into a longer, coherent story instead of relying on the "he said that he said that he said that he said" that is the current blogosphere. Theoretically, it would be able to synthesize over broader and deeper sets of data due to the increased temporary RAM compared to a human brain.
On an unrelated note, if you haven't already, check out the book God's Debris by Scott Adams. Yes, that's Scott Adams the Dilbert comic guy. It has some interesting ideas and even some pertaining to AI. It's also a free download.
The hope of AI is the hope that we will eventually have a technology that can synthesize all these threads of information from the original sources into a longer, coherent story instead of relying on the "he said that he said that he said that he said" that is the current blogosphere. Theoretically, it would be able to synthesize over broader and deeper sets of data due to the increased temporary RAM compared to a human brain.
On an unrelated note, if you haven't already, check out the book God's Debris by Scott Adams. Yes, that's Scott Adams the Dilbert comic guy. It has some interesting ideas and even some pertaining to AI. It's also a free download.
Wednesday, January 17, 2007
1
An Unnatural Birth Has Occurred

In other primate news, a female chimpanzee at the Chimp Haven Home for Former Research Animals has given birth to a baby girl [Source]. This is surprising due to the fact that all of the chimp males at the facility have had vasectomies. Management at Chimp Haven is now planning to do DNA testing on all of the chimp males in order to identify the cause of the unauthorized birthing.
However, this testing is largely unnecessary as I am already certain as to what the results will be. If I can call to your attention that case documented in the film Jurassic Park, this is obviously a case of where the genetic experimentation that has been conducted on these former lab animals has permanently altered their DNA. Hence, resulting in the activation of the latent reptilian genes, producing a sex-reversal of the female specimens, and ultimately spawning the creation of the super-raptors, er, monkeys.
I, for one, welcome our new mutant-monkey overlords.
Thursday, November 16, 2006
11
Using Google Calendar in Microsoft Outlook


I've recently started using the Google Calendar as my main calendaring application. It's neat because its accessible wherever I go, and you can easily add appointments from email messages if you use Gmail. However, when I'm using my notebook, I like to use Outlook for email so that I can keep copies of everything locally. So, I started searching for a way to integrate Outlook with Google Calendar, and found this [link: Incorporate Google Calendar in Outlook]. It's a nice solution, but it involves downloading pieces of M$ crapware (Visual Studio 2005 Tools for Office Runtime, Office 2003 Update: Redistributable Primary Interop Assemblies) and an Outlook plug-in.
I, not a huge fan of installing unnecessary stuff, found a much easier way to integrate GCalendar with Outlook that is enough to meet my needs and requires installing nothing.
Behold!
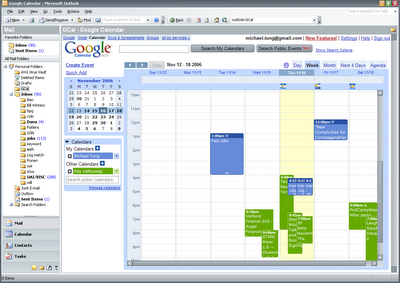

How it's done:
- In Outlook, right-click on the folder you want the GCal link to be in and do "New Folder...". Call it whatever you like.
- Right-click on your newly created folder and select "Properties...". Under the "Home Page" tab, put in the address of Google Calendar (http://www.google.com/calendar/render?pli=1) and select "Show home page by default for this folder."
- Click ok, you're all done.
One drawback of this method, is that you are not really using the Outlook calendar, so its not really a solution for you folks in corporate world on MS Exchange. But if you're happy using Google as your main calendar store, this'll be fine!
Wednesday, September 20, 2006
0
When Disgruntled Laptops Attack Their Masters
So, this is what happened at work this morning. I think the pictures are pretty self-explanatory. Apparently, the smoke detectors in our 8-story tower are only for decorative purposes, since despite the thick black smoke and smell, nothing happened until someone manually pulled on the fire alarm. Comforting, eh?
 On the other hand, my personal notebook is a Dell, too, that I've been using almost 4 years with no problems.
More coverage here:
Valleywag
 On the other hand, my personal notebook is a Dell, too, that I've been using almost 4 years with no problems.
More coverage here:
Dell battery explodes at Yahoo HQ, hundreds evacuate (Engadget)
Flickr shots of the eventValleywag
Thursday, May 11, 2006
5
The Right Cognitive Testbed for AI - Babies
The AI community has had a hard enough time defining what AI is, let alone defining milestones for achieving a functional AI. I believe that the obvious choice for funtional milestone is to achieve a functional AI equivalent of a newborn child. You might think this is a quite natural choice, but it differs from a lot of historical "milestones" of the AI community. An effective robotic baby is not going to help streamline your corporate environment, drive a war vehicle through enemy desert terrain, or handle urban assault situations. But then again, if you don't think a baby can cause mass destruction, you haven't spent enough time with one.
It's uncertain whether developing a functional baby cognitive model is the right direction towards human-level adult AI, but at least the progress is measureable, which can't be said for a lot of other approaches, such as animal models, games, or Turing-test-like setups. For example, just look at how the competition to create a Turing-test passing chat bot has turned out. Has creating a world champion chess computer advanced our knowledge at all of building a human-like AI? Not by much.
Below I have a timeline of an infant's cognitive development up to 1 year, and my own comments on what AI work is involved in emulating that functional behavior.
The ability to detect changes also implies the ability to filter out what's old. i.e. pattern recognition. Old things are, by definition, things that fall into a pattern. So, I believe that the first step of AI is to have generalized pattern recognition(knowing what's old) and differencing(tracking the new changes).
sources:
[1]Gizmodo-Seeing the world through the eyes of a baby
[2]Yahoo! Health-Cognitive development between 1 and 12 months of age
It's uncertain whether developing a functional baby cognitive model is the right direction towards human-level adult AI, but at least the progress is measureable, which can't be said for a lot of other approaches, such as animal models, games, or Turing-test-like setups. For example, just look at how the competition to create a Turing-test passing chat bot has turned out. Has creating a world champion chess computer advanced our knowledge at all of building a human-like AI? Not by much.
If you buy into my arugment so far that the baby model is the right approach, what does it actually involve? I will try to break down what I think the work in this track involves. I've citied the sources of the information at the end of this article.


This image shows how a baby's developing eye sees the world.
Below I have a timeline of an infant's cognitive development up to 1 year, and my own comments on what AI work is involved in emulating that functional behavior.
- Between 1 and 2 months of age, infants become interested in new objects and will turn their gaze toward them. They also gaze longer at more complex objects and seem to thrive on novelty, as though trying to learn as much about the world as possible.
The ability to detect changes also implies the ability to filter out what's old. i.e. pattern recognition. Old things are, by definition, things that fall into a pattern. So, I believe that the first step of AI is to have generalized pattern recognition(knowing what's old) and differencing(tracking the new changes).
- At around 3 months of age, infants are able to anticipate coming events. For example, they may pull up their knees when placed on a changing table or smile with gleeful anticipation when put in a front pack for an outing.
- At around 4 months, babies develop keener vision. Babies' brains now are able to combine what they see with what they taste, hear, and feel (sensory integration). Infants wiggle their fingers, feel their fingers move, and see their fingers move. This contributes to an infant's sense of being an individual.
- Between 6 and 9 months of age, synapses grow rapidly. Babies become adept at recognizing the appearance, sound, and touch of familiar people. Also, babies are able to recall the memory of a person, like a parent, or object when that person or object is not present. This cognitive skill is called object permanence.
- Babies observe others' behavior around 9 to 12 months of age. During this time, they also begin a discovery phase and become adept at searching drawers, cabinets, and other areas of interest. Your baby reveals more personality, becomes curious, and demonstrates varied emotions.
sources:
[1]Gizmodo-Seeing the world through the eyes of a baby
[2]Yahoo! Health-Cognitive development between 1 and 12 months of age
Monday, May 08, 2006
1
LED Letters!
 Want to use a cool LED-looking font while fooling spammers? Read on..
The other day I was doing some work in Javascript, to try to fix some things in Diffbot, when I re-discovered a cool thing about element borders in HTML. Adjacent borders actually come together at a 45° angle in most browsers. Here's what I mean:
This is a div element with borders.
Now, if you take two of these blocks and simply stack them on top of each other, you get a pattern that resembles the LED "8":
makeText("hello", parentElement);Below you see an example output:
Try to select the above "hello" with your mouse--it's neither an image nor text.
The interesting thing about this is that you can use it to make text without actually having that text in the source code. This is great for preventing crawling robots and spammers from reading your text, while still allowing your human readers too see things fine. Some applications of this might be to cloak or email address, generate CAPTCHAs, or to do evil search engine optimization by hiding text from Googlebot. This method might be better than the straightforward method of rendering your text as images because it requires the robot/spammer to have
- a javascript interpreter/browser
- the ability to snapshot/render a certain region of the screen
- Optical character like recognition capability
Monday, April 10, 2006
0
The Nerve Center that is SF
Here's a video where someone did an interesting thing. They graphed the locations of every Yellow Cab equipped with GPS in San Francisco over the course of a day. The intensity of the red represents how fast the cab is going.
Doesn't this remind you of the videos of nerve firings in the brain?
http://clients.stamen.com/cabspotting/cabspotting_01.html
Doesn't this remind you of the videos of nerve firings in the brain?
Tuesday, March 14, 2006
2
Diffbot Invites
 As I mentioned before, I'm launching a new website called Diffbot on April 1st. Diffbot is a cool new kind of web-based RSS reader and bookmark manager. Have a handful of sites that you read daily? Diffbot lets you know when those sites have updated and only shows you the portion that changed. It's also just a convenient place to put your bookmarks so that they are accessible wherever you go. This is still very much a work in progress, so we'd really appreciate any feedback on how we could do better. You can now signup to get an invite when it's ready!
Thursday, March 09, 2006
5
Engineering Software
 Many of my technical readers out there have job titles that match the regular expression "(Sr.|Jr.)? Software Engineer (I)*". For the non-geek readers, that means we call ourselves "Software Engineers" :-). But, what would you consider the difference is between someone who is a "Software Engineer" and someone who's title is a "Computer Programer"? They seem like similar lines of work, yet one seems to imply a higher level of education, perhaps at least a 4-year college instead of a technical trade school. Historically speaking, there has been a huge difference between an engineer and a programmer. During the second World War, "computers" where actually women that caculated artilliary projections using desk calculators. These women became the first computer programmers when they were assigned to program the ENIAC, a room-sized computer with 18,000 vacuum tubes. Engineering, on the other hand, implied not the people that operated the machines, but those that designed the system and solved the larger problems.
Most major universities separate the School of Engineering from the School of Sciences. Engineering includes departments like chemical, mechanical, nuclear, bio and electrical engineering. Science includes departments like chemistry, physics, biology and computer science. Although, it seems like there's a lot of duplication here with the sciences, supposedly, this is because engineering has some common skillset. Engineering cirricula require a certain type of maths. Engineers usually study topics like design, tolerances, robustness, production processes, and technical writing.
However, let's return to what is software engineering? One of the most popular degrees that Software Engineers graduate with is Computer Science, which is not an engineering degree. What I'd like to argue--and this point has been made before--is that software engineering, is not only not taught in formal education, but is consequently different from the other types of engineering. This is why large companies recruiters complain about fresh college grads knowing nothing about debugging, why there are so many software internships, why most software engineering jobs require a few to several years of prior experience--its because that's when you actually learn some "software engineering"!.
 However, I say software engineering is fundamentally different from other types of engineering, because the field itself is still in its prenatal state. Maybe that is one of the reasons why it hasn't been developed yet in formal education; we don't really know yet what are the best practices and fundamental formulas in software engineering. The level of engineering that goes into building even the largest software projects is nothing like the level of engineering that goes into building something like a car. It's more like the amount required to build a snowman. Even when I was working at Microsoft on the Windows source code, the Hoover Dam of software engineering, there was very little engineering in place to manage the complexity and uncertainty. To get a sense of this, compare the reliability of your office buiding to Microsoft Office. If your plumbing system or electric system failed as much as my MS Outlook or Firefox crashes, you would be a very unhappy camper. Yet for information workers, both things are equally important to their day.
Software engineering is a newer discipline than mechanical engineering, or even electrical engineering. Obviously, the software world is undergoing a very rapid change right now. We haven't had time yet to sit back and understand the principles and fundamental formulae that govern software. There are lots of well-specified problems, where there is no agreement on what is the best algorithm. Sure, there are small groups of people every studying problems like software reliability, static source code analysis to identify software weaknesses, and theoretic guarantees for software correctness and performance. I think these efforts will become increasingly important.
I've explained in my mind what the distinction between software and other forms of engineering are, but why do I think this is an important issue? There's no problem with working in a field that is largely unstructured, complex, and ad-hoc. That's part of the excitement of being in a brand new field. Life is great as a software engineer. The problem is that software is increasingly replacing the function of physical objects and electrical components. That is, computers are used to replace other things. Your typewriter has been replaced by your word processor. The control center of your car has been replaced by a small computer running an embedded operating system. Your telephone has been replaced by a small computer which emulates the phones functions. The stock market itself has been infused with tons of small programs, trading trillions of your dollars. Take the typewriter as an example, the mechanical engineer that designed it knows that unless the few joints between the key and the hammer fail, your keystroke will translate into a mark on the paper. The materials in the product have been carefully chosen with respect to their well known structural flexibility, strength, and mass. I won't even begin to explain all the things that could go wrong between the time you hit a key on your computer and see a letter appear on screen. In this "design", the components involved were chosen because they seem to work. It's crazy talk to try to estimate how reliable this design is. Yet, this fundamental unreliability is what we entrust to keep our airplanes in the air, our cars on the highway, our bank accounts and financial markets secure. It's just a matter of time before a catastrophic software failure occurs (many major ones already have), or we decide to design responsible software. Software that works as reliably as a toaster. Software that just doesn't break, no matter what the user does.
Most Popular Posts:
Ranking Colleges Using Google and Open Source
Tuesday, February 28, 2006
1
What is Web 2.0 ?
Everyone in the sphere seems to have an opinion on what Web 2.0 means to them, and I will add my own here. Web 2.0 is the new software tradition which we have all but transitioned to. The features of this new tradition that differentiate it from the older tradition are that products are more focused on design rather than on capability/features. Take for example products like Flickr, Firefox, MacOS X, Office 12, and the slew of AJAX service-based microapps. A good example to illustrate this paradigm shift is MS Word. In earlier versions of Word(1-7), each release added more capability to the editor evolving it from something like Notepad to the current Word 2003, while essentially keeping the interface consistent and familiar. However, if you look at Word 12, the first thing you will notice is a new interface focused on making tasks more efficient and discoverable. Even the data is stored in open formats with the goal of making it easy to consume and access by third parties.
Why did this shift occur and does this mean that software companies will eventually evolve into pure design companies? It's conceivable that with technology becoming more and more accessible and the wider availability of powerful tools, the software company of the future may be staffed almost completely with artists, psychologists, anthropologists, and designers, with maybe a few technical school graduates to write the tools.
And also, why is it that features and capabilities are less emphasized now? Aren't those the cornerstone of the computer revolution--being empowered by technology?
The truth is, the software industry is stuck in a rut. You can see it across all specialties--office productivity software, on the web, in gaming--no new features have been added, no new types of websites, no new gameplay, just more efficiency, more polygons, more psuedo-chrome. Since we have no new features to add, we have been keeping busy by making things pretty and usable, to keep us employed. Why this rut? Some might say that it is because the industry has entered a stage of evolution rather than revolution. We've reached a critical mass where now the improvements will be in small increments. I agree and also disagree. I agree that is the state of the industry, but I think the cause for no new features is simply that we have no new technology.
Technology as a whole, even outside of IT, has actually slowed down. Where are the Bell Labs of today? PARC is a shell of its former self. What are the new Information theories and quantum theories, new internets. Technology innovation has flatlined after it was made unecessary after we came out of wartime. The internet itself is a wartime child.
Okay, I've gotten a little too caught up and started rambling, but I think the solution to this technological rut is clear. We need more fundamental research. We've reached the limit on how far we can milk the results of past research. Whether or not there is a wartime neccessity, we need to do this basic research in order to improve the capabilities of our systems, to claim that things are still getting better.
So, what kind of new capabilities should be developed? Computers today are used almost solely to input, output, store, or transmit human data. But, instead of just being repositories and pipes for the data, I believe computers can consume and reason with data, much like a human can. How this can be implemented in our current market, I'll talk about later.
Why did this shift occur and does this mean that software companies will eventually evolve into pure design companies? It's conceivable that with technology becoming more and more accessible and the wider availability of powerful tools, the software company of the future may be staffed almost completely with artists, psychologists, anthropologists, and designers, with maybe a few technical school graduates to write the tools.
And also, why is it that features and capabilities are less emphasized now? Aren't those the cornerstone of the computer revolution--being empowered by technology?
The truth is, the software industry is stuck in a rut. You can see it across all specialties--office productivity software, on the web, in gaming--no new features have been added, no new types of websites, no new gameplay, just more efficiency, more polygons, more psuedo-chrome. Since we have no new features to add, we have been keeping busy by making things pretty and usable, to keep us employed. Why this rut? Some might say that it is because the industry has entered a stage of evolution rather than revolution. We've reached a critical mass where now the improvements will be in small increments. I agree and also disagree. I agree that is the state of the industry, but I think the cause for no new features is simply that we have no new technology.
Technology as a whole, even outside of IT, has actually slowed down. Where are the Bell Labs of today? PARC is a shell of its former self. What are the new Information theories and quantum theories, new internets. Technology innovation has flatlined after it was made unecessary after we came out of wartime. The internet itself is a wartime child.
Okay, I've gotten a little too caught up and started rambling, but I think the solution to this technological rut is clear. We need more fundamental research. We've reached the limit on how far we can milk the results of past research. Whether or not there is a wartime neccessity, we need to do this basic research in order to improve the capabilities of our systems, to claim that things are still getting better.
So, what kind of new capabilities should be developed? Computers today are used almost solely to input, output, store, or transmit human data. But, instead of just being repositories and pipes for the data, I believe computers can consume and reason with data, much like a human can. How this can be implemented in our current market, I'll talk about later.
Tuesday, February 14, 2006
0
Ranking Freedom of Press
Here's another interesting ranking: the World Press Freedom Index. The list is topped by Denmark. At the bottom of the list is North Korea. The US? 44th. Another interesting data point is the United States of America (in Iraq) [sic] listed with rank 137. Defenders of freedom?
Sunday, February 12, 2006
1
Using Statistics to Uncover Human Rights Violations
The Human Rights Data Analysis Group , which used to be incubated under AAAS has just released a study they did on the analysis of the human rights violation datasets from Timor-Leste. I'm poring over their paper right now
The Profile of Human Rights Violations in Timor-Leste, 1974-1999
A Report by the Benetech Human Rights Data Analysis Group to the Commission on Reception, Truth and Reconciliation of Timor-LesteThe actual datasets are available for download as well. I encourage you to check them out(zipped CSV files):
The Profile of Human Rights Violations in Timor-Leste, 1974-1999
A Report by the Benetech Human Rights Data Analysis Group to the Commission on Reception, Truth and Reconciliation of Timor-LesteThe actual datasets are available for download as well. I encourage you to check them out(zipped CSV files):
the graveyard census database, called the Graveyard Census Database (GCD)
the fatal violations data from the Retrospective Mortality Survey (RMS)
the Multiple Systems Estimation (MSE) data file
Wednesday, February 08, 2006
0
Diffbot Launch Date
 Some of you may know that I've been working in my spare time on a new type of news reader. Until now, the service has been a closed test involving about 50 users. Last week, though, Leith and I have finally decided on a launch date for a public beta. It's going to be April Fools Day, 2006. That gives us less than two months to get things tidy (and boy are there a lot of things!). Stay tuned...
Tuesday, February 07, 2006
1
Ask the Geek Grammar Lady #1
In the course of working with fellow geeks, I've noticed a few language usages that are unique to us geeks. One of these is the tendency to classify problems and issues as either "trivial" or "hard". Now, you have to understand, part of this standard geek colloquialism comes from the math tradition of formal proofs. Trivial is used to describe the obvious, non-interesting solution. "Hardness" could be a shortening of NP-hard, used to describe a class of problems that requires a lot of computation.
Next time you are tempted to use these labels, maybe consider some of the following more meaningful alternatives:
Instead of "This such-and-such problem is trivial"... consider replacing it with:
Next time you are tempted to use these labels, maybe consider some of the following more meaningful alternatives:
Instead of "This such-and-such problem is trivial"... consider replacing it with:
- This such-and-such problem is easy to solve!
- This such-and-such problem is small in scope.
- This such-and-such problem is easy to talk about, but would require a team of grad students 10 months to implement.
- So, we all know such-and-such is computationally intensive.
- So, we all know such-and-such is impenetrable.
- So, we all know such-and-such is something I have no idea how to do.